 By Alpit Patel and the aibrevo team · September 11, 2026 · Updated October 8, 2026 · 20 min read
Salesforce Data Migration Plan: Steps, Tools and Cost
Migrating to Salesforce means mapping your data into its object model, rebuilding automation in Flow and Apex with governor limits in mind, and testing at real volume in a sandbox, not exporting records and hoping the logic follows.
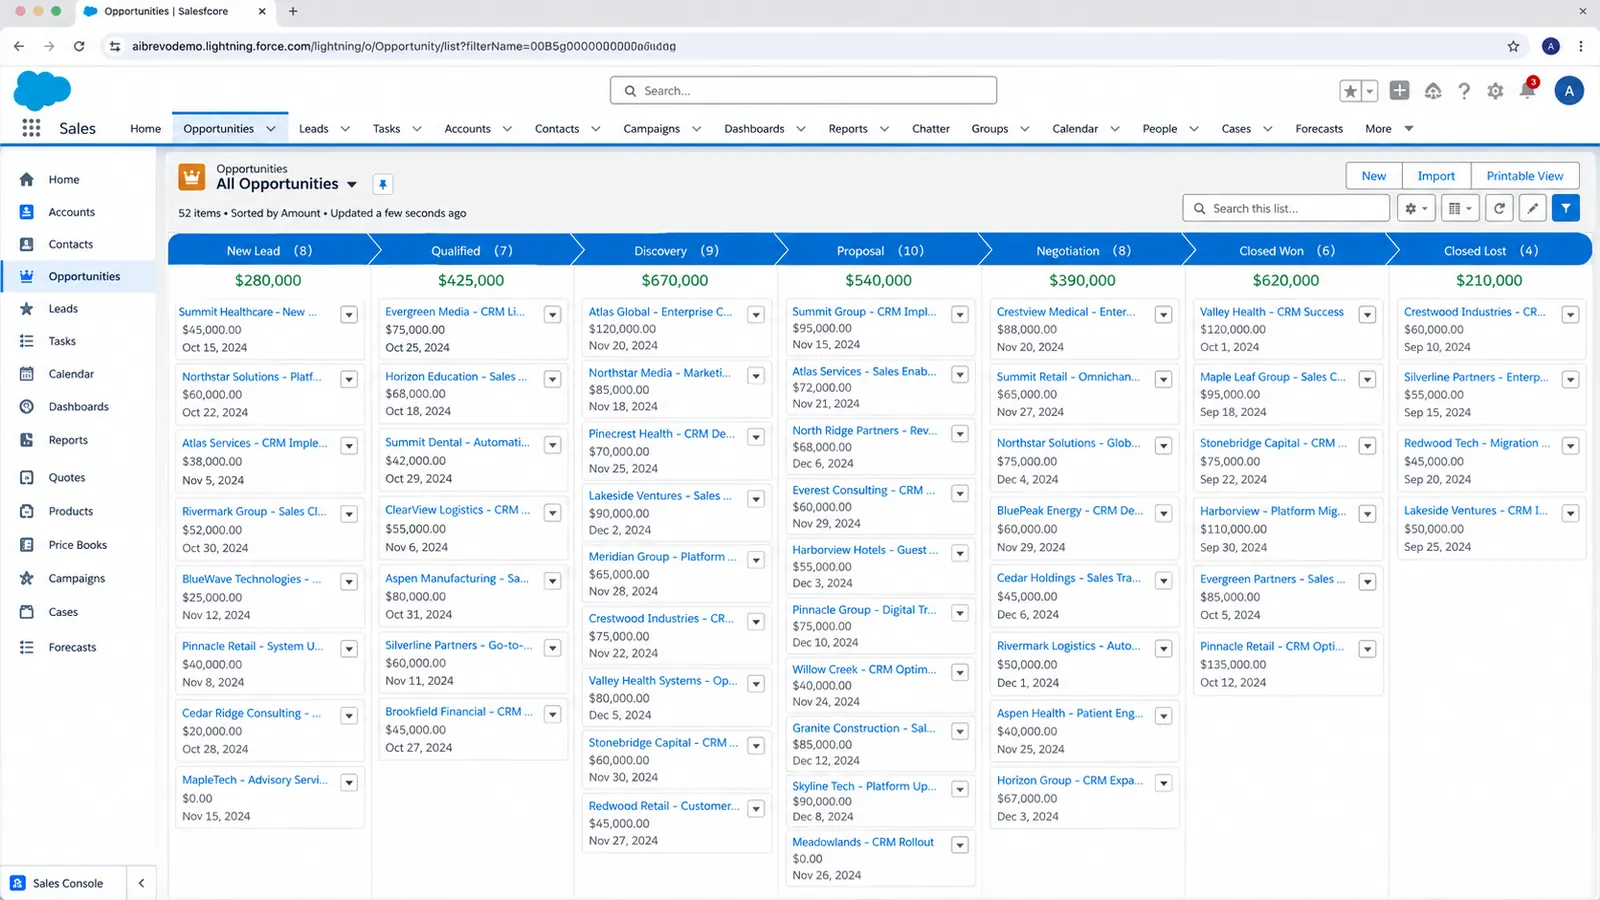
Part of the guide: CRM migration guide
Key takeaways
- Salesforce migrations succeed or fail on object-model mapping, not data volume: deciding how source records become Accounts, Contacts, Leads and Opportunities has to happen before a single record moves.
- Automation rebuilt without bulkification in mind is the single most common way a Salesforce migration that 'worked in testing' breaks under real production volume.
- Data migration and mapping run roughly 15% of a typical Salesforce implementation budget, while integration and custom development (Apex, API work) absorb the largest share at roughly 30%; customization, not the data move itself, is usually the bigger cost driver.
- A median of published agency and partner price pages (checked October 2026) puts small-business Salesforce implementation at $10k-$25k, scaling to $40k-$150k mid-market and $150k-$400k+ for a multi-cloud enterprise build; seat count moves this far less than Apex development and cloud count.
- Sandbox testing at realistic data volume, with actual end users checking their own records and reports, catches the issues that a 200-record test migration never surfaces.
A typical Salesforce migration timeline by phase: proportional, not a fixed schedule. Data volume and automation complexity shift these percentages meaningfully.
Migrating to Salesforce means mapping your data into Salesforce’s object model (standard objects, custom objects, and the relationships between them) and rebuilding your automation in Flow and Apex, because the old logic won’t translate directly. Teams that treat it as a pure data-export exercise usually end up with a system that holds the old data but does not reflect the old process. If you haven’t fully committed to Salesforce yet, the HubSpot vs Salesforce comparison and the platform-agnostic CRM migration guide are worth reading first; this guide assumes Salesforce is the confirmed destination.
What does a Salesforce data migration plan look like?
A Salesforce data migration plan is nine steps in a fixed order: map objects, clean the source, choose the load tool, set org-level options, load in parent-before-child order, test in a sandbox, validate, cut over, then audit after go-live. Each step below links to the section that covers it in depth.
- Map source records to Salesforce objects. Decide which source records become Accounts, Contacts, Leads and Opportunities, and which fields are dropped. See how to map data for a Salesforce migration.
- Clean and deduplicate the source data. Fix picklist spellings and merge duplicates before they load. See deduplication with Salesforce’s tools.
- Decide the org settings you cannot undo. Person Accounts, multi-currency and state/country picklists. See org-level settings to decide before migration.
- Choose the load tool. Data Import Wizard, Data Loader or Bulk API, by record count. See which tool to use.
- Rebuild automation inside governor limits. See rebuilding automation.
- Pick and refresh a sandbox. See which sandbox type you need.
- Run the full load in the sandbox and validate. Row counts per object, then user checks. See testing a Salesforce data migration in a sandbox.
- Cut over. Freeze the source, run the final delta, move files, watch API limits. See planning the cutover and files, attachments and API limits.
- Audit after go-live. Spot-check records against the source for at least a week and confirm integrations are sending data.
For the money side, see what migrating to Salesforce typically costs. If your source is Pipedrive, the sibling Pipedrive to Salesforce migration guide owns that route.
How do you map data for a Salesforce migration?
Salesforce structures data around standard objects (Account, Contact, Opportunity, Lead) plus any custom objects you build. Before migrating, decide how your source data maps onto this structure: a “Company” in your old system usually becomes an Account, but the mapping isn’t always that clean, especially for platforms with a flatter data model (a single “Contact” that combines what Salesforce splits into Lead and Contact, for example). Get this mapping documented and reviewed before any data moves, since restructuring relationships after records are loaded is far more painful than mapping correctly the first time. Coming from Pipedrive specifically? The Pipedrive to Salesforce migration guide covers mapping Pipedrive’s data model to Salesforce before import.
In practice this means walking through every field in the source system and assigning it one of four outcomes: maps directly to a standard field, maps to a new custom field, gets combined with another field during transformation, or gets dropped because it no longer reflects the process. Teams that skip the “drop” category tend to recreate every field their old CRM accumulated over years, including the half-used ones nobody reports on, so the clutter comes along too. The mapping document should also flag picklist values that need normalizing (three spellings of “Enterprise” is a common find) before they become three different values in a Salesforce picklist.
Migrating from a flat CRM (HubSpot, Pipedrive) is a bigger structural project than migrating between two enterprise systems
Does moving from HubSpot or Pipedrive to Salesforce need different mapping work than an enterprise-to-enterprise migration? Yes, and it’s the part most migration quotes underscope. HubSpot and Pipedrive are both built around a single flexible object (a “deal” or a “contact” with custom properties layered on). Salesforce uses a relational model of separate Lead, Contact, Account and Opportunity objects tied together by lookup relationships. A HubSpot deal with a company name typed into a text field doesn’t automatically become a linked Salesforce Account; someone has to decide whether that text field becomes a new Account, gets matched against an existing one, or gets dropped in favor of a cleaner re-entry.
That extra structural step means the mapping document for a flat-CRM migration needs an explicit pass just for splitting combined data into the right target objects, on top of the field-by-field mapping every migration needs. Skipping this pass is exactly how teams end up with a Salesforce org full of Opportunities with no linked Account, which quietly breaks account-level reporting and territory assignment the day someone tries to run either. If HubSpot is specifically where you’re migrating from, the HubSpot migration guide and HubSpot to GoHighLevel migration guide cover source-side considerations that complement the Salesforce-side mapping work described here.
Plan record types and page layouts around real usage, not defaults
If different teams or products need different fields and processes, Salesforce’s record types and page layouts handle that, but only if you plan them before migration. Decide up front whether you need multiple record types (e.g. separate Opportunity record types for new business versus renewals), because migrating everything into one generic layout means retrofitting structure later.
A useful test: if two teams selling different products would answer “what fields matter on this record” differently, that’s a signal for separate record types and page layouts. One shared layout would leave optional fields that everyone scrolls past. Getting this wrong in the other direction (too many record types for processes that are actually identical) creates its own maintenance burden, since every record type needs its own page layout, validation rules and often its own sales-process picklist values to keep in sync.
What migrating to Salesforce typically costs, by company size
Salesforce’s implementation cost range is wide because “Salesforce” can mean a single-cloud, lightly customized rollout or a multi-cloud build with Apex development and a dozen integrations. The chart below shows the cited industry cost range by company size:
The enterprise bar has by far the widest range ($150k to $400k+). That spread comes from Apex development, multi-cloud scope (adding Service Cloud or CPQ on top of Sales Cloud) and integration count, with seat count playing little part. A 100-user org with a clean, single-cloud setup can land near the low end of the mid-market range, while a 20-user org running CPQ and three system integrations can land near the enterprise ceiling. Where your migration falls depends on scope, so a scoping call is the way to find out.
Rebuild automation with governor limits in mind
Workflow rules, email alerts and approval processes from another platform don’t transfer; they need to be rebuilt in Flow (and Apex where the logic requires it), and rebuilt correctly means respecting Salesforce’s governor limits from the start: bulkified triggers that handle batches of records, since one-at-a-time loops hit API call limits under real production volume. This is the single most common place migrations that “worked in testing” break once real usage hits them.
Salesforce’s own Apex governor limits reference sets the specific ceilings that trip up rebuilt automation: 100 SOQL queries per synchronous transaction (200 in an async context), 150 DML statements per transaction, a 10-second CPU time limit, and a 6 MB heap size. A trigger written to query or update one record at a time can look identical in a code review to one that batches correctly; the difference only shows up when a bulk import, a mass reassignment, or a marketing sync pushes 500 records through the same trigger in one transaction and the per-transaction query count blows past 100. Designing the rebuilt automation against these specific numbers is what lets a migration survive its first real bulk operation.
Industry research into CRM implementation failure consistently finds technology accounts for a small share of the problem: one 2025 analysis of CRM project outcomes put the overall CRM implementation failure rate at 55%, with more than 60% of failures traced to people and process issues (poor user adoption, unclear ownership, weak change management), against roughly 10% attributable to the technology itself. Most of the migration risk comes from skipping the mapping, governor-limit, and adoption work in this guide.
Before rebuilding a single automation, list every workflow, notification and approval step the old system runs and mark which ones actually still reflect how the team works today versus which ones accumulated as one-off exceptions nobody remembers the reason for. Rebuilding a legacy exception exactly as it existed is how a clean Salesforce org quietly inherits the same automation sprawl the old CRM had; this is the moment to prune. For anything that touches more than a handful of records at once (a nightly sync, a mass status update), design it from the outset as a batch or queueable Apex job. A synchronous trigger starts throwing limit exceptions the day record volume doubles, and a batch job scales.
Which tool should you use for a Salesforce data migration?
Salesforce gives you three different tools for loading data, and picking the wrong one for your data volume is a common source of migration delay. The point-and-click Data Import Wizard, built into Setup, handles up to 50,000 records per object and is meant for genuinely simple loads with minimal transformation, fine for a short list of custom objects but too small for a full CRM migration. Data Loader, Salesforce’s free desktop and CLI tool, can run against the standard SOAP API for smaller batches or against the Bulk API for real volume: Bulk API processes records asynchronously in batches (2,000 records per batch by default, configurable up to 10,000), which is what makes it practical to move hundreds of thousands of records without the load timing out or hitting per-transaction limits the way a synchronous load would. If you are moving into Salesforce from a smaller CRM, the CRM import limits comparison shows how the wizard’s 50,000-record ceiling compares with other platforms.
In what order should you load Salesforce objects, and with which tool?
Load parents before children, because a child row needs the Salesforce ID (or an external ID) of the record it points to. The table gives the usual order and which tool fits each object. Tool limits are from Salesforce’s own pages, checked 2026-10-14.
| Order | Object | Why this position | Data Import Wizard? | Data Loader / Bulk API |
|---|---|---|---|---|
| 1 | Users, record types, picklist values | Owners and record types must exist before any record names them | Not applicable | Setup, not a data load |
| 2 | Accounts | Parent of Contacts and Opportunities | Yes (up to 50,000 records at a time) | Yes |
| 3 | Contacts | Needs the Account to exist | Yes | Yes |
| 4 | Leads | Independent of Accounts until converted | Yes | Yes |
| 5 | Products and Price Books | Must exist before Opportunity line items | Not on the wizard’s named list | Yes |
| 6 | Opportunities | Needs Account (and Contact roles after) | Not on the wizard’s named list | Yes |
| 7 | Activities (tasks, events), notes | Point at Contacts, Leads or Opportunities | Not on the wizard’s named list | Yes |
| 8 | Files and attachments | Largest storage hit; load last | No | Yes, watch file storage |
What Salesforce publishes about the tools:
- Data Import Wizard: “It can import up to 50,000 records at a time.” It covers “accounts, contacts, leads, solutions, person accounts, or campaign members” plus custom objects, per Salesforce Trailhead. Objects outside that list, including Opportunities, are not named there, so plan on Data Loader for them.
- Data Loader: Trailhead says it “can import up to 150 million records at a time, of any data type,” through the interface or the command line.
- Bulk API and Bulk API 2.0: Salesforce’s limits cheat sheet lists 15,000 batches in a rolling 24 hours (shared between the two APIs), a maximum of 10,000 records per batch in Bulk API, and 150,000,000 records per 24 hours. Bulk API 2.0 is capped at 150 MB per job after base64 encoding; Salesforce advises keeping uploads under 100 MB.
The object order is standard relational practice, and Salesforce does not publish a sequence. Salesforce’s help site is rendered by script and could not be read directly, so confirm edition-specific limits in Setup before a large load.
Reference data (Accounts, then Contacts that depend on them) has to load before the records that reference it (Opportunities, Cases), because Salesforce’s relational model means a child record referencing an Account that doesn’t exist yet either fails or loads without the relationship intact. A migration plan that loads objects in dependency order and validates row counts and a sample of relationships after each object loads catches a broken mapping in the object where it happened. Without those checks, the problem shows up three objects later, when a report turns up empty relationships with no obvious cause.
What is a sandbox, and which type do you need to test in?
A Salesforce sandbox is a copy of your org used for testing that isolates the test from live production data, and which type you use changes how realistic that test actually is. A Developer sandbox gives a small amount of storage and no production data at all, which suits testing automation logic in isolation but will miss volume-related issues. A Partial Copy sandbox pulls a defined sample of production data using a sandbox template you configure, giving a more realistic (if still partial) test. A Full sandbox copies the entire production org, including all data, the only sandbox type that reliably surfaces the issues (governor-limit breaches, report and dashboard behavior at real volume, sharing-rule edge cases) that a smaller test environment structurally can’t show you, per Salesforce’s own sandbox documentation.
Full sandboxes take longer to refresh (Salesforce enforces a minimum refresh interval, commonly cited around 29 days) and cost more than Developer or Partial Copy sandboxes, which is why many teams default to a smaller sandbox type to save time and then discover volume-related issues only after go-live. For a migration specifically, the tradeoff is worth making deliberately: a Full sandbox test costs more calendar time up front but is the only environment where “does this survive real production volume” gets a real answer before it’s your live org finding out.
Handle deduplication with Salesforce’s tools
Salesforce has built-in duplicate rules and matching rules that can catch new duplicates going forward, but they don’t retroactively clean data that’s already messy at import. Run de-duplication on the source data before migration (see the general CRM migration guide for the process), then configure Salesforce’s duplicate rules to prevent the same mess from recurring after go-live.
Matching rules typically compare on fuzzy criteria (company name similarity, email domain, phone number format), and it’s worth tuning these deliberately. A matching rule set too loosely flags legitimate separate accounts (two different companies that happen to share a common word in their name) as duplicates and trains users to ignore duplicate warnings entirely; one set too tightly lets real duplicates back in within weeks of go-live.
Decide, object by object, whether a duplicate rule should block the save entirely, warn but allow it, or just report on it after the fact. Blocking makes sense for Accounts and Contacts, where a duplicate genuinely causes downstream reporting problems. A warn-only rule is usually the better call for Leads early after go-live, since Lead volume from marketing sources tends to produce enough near-duplicates that a hard block would frustrate reps faster than it prevents real mess, and warn mode still gives you the data to tighten the rule once you see what it’s actually catching.
Which org-level settings have to be decided before migration, because they can’t be changed later?
A handful of Salesforce settings are effectively permanent once your org has live data in it, and getting caught by one after migration is far more expensive than deciding it up front. Person Accounts is the clearest example: it’s an org-wide feature that merges the Contact and Account model for B2C-style records (a single person who is also the account), and Salesforce does not offer a clean, supported way to turn it on for an org that already has standard Business Accounts with real data in production. If your business sells directly to individual consumers (a med spa, a real estate brokerage working with buyers directly, a financial advisory practice), decide whether Person Accounts fits your model before the first record loads, because reversing that decision after go-live typically means a second, disruptive data migration.
Currency works the same way at a smaller scale. A single-currency org can be converted to multi-currency, but the reverse isn’t true, and once multi-currency is enabled you’re committed to it as an org-wide setting even for teams that never touch international deals. Enabling multi-currency you don’t need adds a currency field and conversion-rate maintenance to every currency-aware object in the org for no benefit; not enabling it when you do need it means a migration project later, once the first international deal already needs updated exchange rates that don’t exist. State and Country picklists carry a similar one-way quality: Salesforce’s newer picklist-based state/country fields replace free-text entry, and switching an org that’s accumulated years of inconsistent free-text state and country data over to picklists after the fact means a cleanup project that’s much cheaper to do once, during migration, than to do twice.
None of these are hard to get right: Salesforce’s own Person Accounts documentation and multi-currency setup guides spell out exactly what each setting does. The risk is that these settings look like minor checkboxes in Setup and get skipped during the mapping and scoping conversation, then surface as a scope-changing problem three months after go-live when the business tries to do something the org-level setting quietly forecloses. Add a short “org settings that can’t change later” checklist to the mapping document specifically so someone signs off on Person Accounts, multi-currency, and state/country picklist format before the migration.
How do you test a Salesforce data migration in a sandbox?
Salesforce sandboxes exist specifically for this: run the full migration into a full or partial sandbox first, using real (anonymized where needed) data volume, and validate reports, dashboards and automation against it before touching production. A migration that looks clean with 200 test records can behave very differently at 50,000 real ones; sandbox testing at realistic volume is the only way to catch that before go-live.
Have actual end users, as well as the admin who built the migration, check their own records, pipelines and reports in the sandbox before cutover. Admins tend to check that the data loaded correctly; sales reps notice when a deal’s stage history looks wrong or a report is missing a filter they rely on daily. Budget real calendar time for this round of user validation. It’s usually where the last real issues surface before they become production problems.
Migrating from an industry-specific process
Salesforce’s flexibility matters most for teams whose sales process doesn’t fit a generic pipeline. A real estate brokerage migrating listing and transaction data, a financial services firm with compliance-driven approval chains, or a manufacturer with a long, quote-heavy cycle involving multiple products per deal will each need custom objects or record types that a generic Sales Cloud default doesn’t provide out of the box. The mapping work described above matters even more in these cases: a “Deal” in a real estate CRM might need to become an Opportunity linked to a custom Property object, and getting that relationship right during migration is considerably cheaper than restructuring it after go-live once reports and dashboards are already built against the wrong shape. For a worked example of rebuilding a quoting process on Salesforce, see the composite logistics CPQ case study, where quote turnaround went from three days to under four hours.
How do you plan the cutover for a Salesforce data migration?
Pick a specific cutover date. In the days before cutover, freeze significant changes to the source system or run a delta sync so the final migration captures everything created since the sandbox test. Communicate the freeze window clearly to the whole team, including everyone beyond the admins; most post-migration complaints trace back to a record created or changed during an undocumented freeze window. After go-live, budget at least a week of close monitoring: spot-check migrated records against the source system, confirm automation fires correctly on real new records, and verify integrations are sending and receiving data before calling the migration complete.
Don’t forget files, attachments, and API rate limits during cutover
Attachments, notes, contracts, and email history sitting on records in the old system need their own migration path, and Salesforce treats file storage as a separate, metered resource from data storage, a detail that’s easy to miss until a migration plan built around record counts alone runs into a storage-limit warning mid-load. Decide early whether historical attachments migrate in full, migrate for a defined recent window only, or stay accessible in a read-only archive of the old system instead of moving at all; migrating years of accumulated file attachments in full is rarely worth the storage cost and load time it adds; most teams migrate current and recent files and leave older ones in an archived export.
The other easy-to-miss mechanic is API rate limits during the cutover window itself. Salesforce enforces a rolling 24-hour API call limit per org, based on edition and user count, and a migration that’s simultaneously running a bulk data load, a parallel integration sync, and manual testing by several team members can hit that ceiling faster than expected, especially on a smaller-edition org. Scheduling the bulk load for a low-traffic window, and pausing non-essential integrations during the load itself, avoids a scenario where the migration and a live integration compete for the same API budget on cutover day.
Where the rest of a Salesforce migration budget goes
Data migration is usually the largest variable within a Salesforce implementation budget; see the Salesforce implementation cost guide for cited industry ranges by company size and the specific cost drivers, including hidden costs like sandbox/environment licensing and AppExchange package fees that a simple license-price comparison misses. License pricing changed too: since September 3, 2026, Salesforce’s public price list goes from Pro Suite straight to the new Core, Advanced and Max editions, so check which edition your migration is targeting before you scope it. Industry cost-phase research also breaks down where the rest of a typical Salesforce budget goes: roughly 30% to integration and custom development (the largest single share), 20% to schema and object design, 20% to sandbox migration and testing, 15% to data audit and mapping, and 15% to UAT and training, a useful reference point when a vendor’s quote allocates the work very differently.
Get your migration scoped
A free 30-minute call reviews your current setup (whatever platform you’re on now) and gives you a written read on what a Salesforce migration for your specific data and process actually involves.
If you keep Salesforce and only need monday.com to read and write its records, see whether monday.com integrates with Salesforce first, including the Enterprise plan and Salesforce edition requirements.